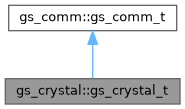
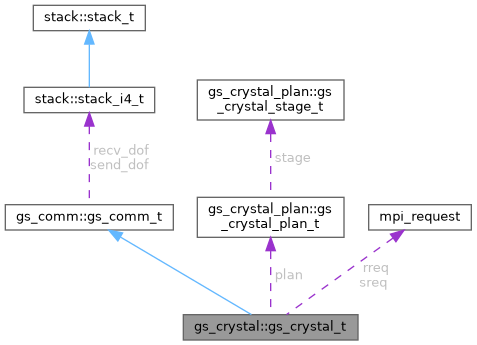
Gather-scatter communication using a crystal router. More...
Public Member Functions | |
| procedure, pass(this) | init (this, send_pe, recv_pe) |
| Initialise crystal router based communication method See gs_comm.f90 for details. | |
| procedure, pass(this) | free (this) |
| Deallocate crystal router based communication method. | |
| procedure, pass(this) | nbsend (this, u, n, tag, deps, strm) |
| See gs_comm.f90 for more details on these routines. | |
| procedure, pass(this) | nbrecv (this, tag) |
| Post the receives of the first routing stage. | |
| procedure, pass(this) | nbwait (this, u, n, op, strm) |
| Drive the remaining routing stages and reduce what is delivered into the shared vector. | |
| procedure, pass(this) | init_vec (this) |
| Allocate the fused vector working and send buffers, sized for GS_VEC_NC components. Deferred to the first fused exchange, see gs_comm_t. The routing plan is shared with the scalar exchange and is not rebuilt here, so this stays rank local. | |
| procedure, pass(this) | nbsend_vec (this, u, n, nc, tag, deps, strm) |
| Pack the shared vector and post the send of the first routing stage, fused nc-component. | |
| procedure, pass(this) | nbrecv_vec (this, tag, nc) |
| Post the receives of the first routing stage, fused nc-component. | |
| procedure, pass(this) | nbwait_vec (this, u, n, nc, op, strm) |
| Drive the remaining routing stages and reduce what is delivered into the shared vector, fused nc-component. | |
| procedure(gs_comm_init), deferred, pass | init gs_comm_init |
| procedure(gs_comm_free), deferred, pass | free gs_comm_free |
| procedure(gs_nbsend), deferred, pass | nbsend gs_nbsend |
| procedure(gs_nbrecv), deferred, pass | nbrecv gs_nbrecv |
| procedure(gs_nbwait), deferred, pass | nbwait gs_nbwait |
| procedure, pass(this) | init_dofs (this) |
| procedure, pass(this) | free_dofs (this) |
| procedure, pass(this) | init_order (this, send_pe, recv_pe) |
| Obtains which ranks to send and receive data from. | |
| procedure, pass(this) | free_order (this) |
| procedure, pass(this) | take_schedule (this, src) |
| Take over the gather-scatter schedule (dof lists and peer order) of src, avoiding a second (expensive) pass over the connectivity. The data is moved rather than copied, so src is left without a schedule and must not be used for communication afterwards (it can still be freed). No communication resources are set up here; complete the handover with init_schedule once src has been freed, so that the two backends never hold their resources at the same time. | |
| procedure, pass(this) | init_schedule (this) |
| Set up this communication method for the schedule taken over by take_schedule. Collective, as init is. | |
| procedure, pass(this) | init_vec (this) |
| Fused vector halo exchange. Default implementations abort; backends that set vec_supported = .true. override them. | |
| procedure, pass(this) | nbsend_vec (this, u, n, nc, tag, deps, strm) |
| Default fused vector send. Abort unless a backend overrides it. | |
| procedure, pass(this) | nbrecv_vec (this, tag, nc) |
| Default fused vector receive. Abort unless a backend overrides it. | |
| procedure, pass(this) | nbwait_vec (this, u, n, nc, op, strm) |
| Default fused vector wait/reduce. Abort unless a backend overrides it. | |
Public Attributes | |
| type(gs_crystal_plan_t) | plan |
| The routing plan, worked out once from the schedule. | |
| real(kind=rp), dimension(:), allocatable | buf |
| Working buffer, two columns of plannwrk laid end to end. Column q starts at (q-1)*plannwrk. | |
| real(kind=rp), dimension(:), allocatable | sbuf |
| Send buffer, plannsmax words. | |
| real(kind=rp), dimension(:), allocatable | buf_v |
| Fused vector working and send buffers, the same layout scaled by GS_VEC_NC components. Positions are interleaved: position p holds its nc components at nc*(p-1) + 1 .. nc*p. | |
| real(kind=rp), dimension(:), allocatable | sbuf_v |
| type(mpi_request), dimension(1) | sreq |
| Requests of the stage in flight, at most one send and two receives. | |
| type(mpi_request), dimension(2) | rreq |
| integer | nsreq = 0 |
| integer | nrreq = 0 |
| integer | tag = 0 |
| Tag of the operation in flight, taken from nbrecv since the later stages are driven from nbwait, which is not given one. | |
| type(stack_i4_t), dimension(:), allocatable | send_dof |
| A list of stacks of dof indices local to this process to send to rank_i. | |
| type(stack_i4_t), dimension(:), allocatable | recv_dof |
| recv_dof(rank_i) is a stack of dof indices local to this process to receive from rank_i. size(recv_dof) == pe_size | |
| integer, dimension(:), allocatable | send_pe |
| Array of ranks that this process should send to. | |
| integer, dimension(:), allocatable | recv_pe |
| array of ranks that this process will receive messages from | |
| logical | vec_supported = .false. |
| Whether this backend implements the fused vector (multi-component) halo exchange (nbsend_vec/nbrecv_vec/nbwait_vec). When .false., the gs_op_r3 caller falls back to nc independent scalar exchanges. | |
| logical | vec_ready = .false. |
| Whether the buffers the fused vector exchange needs are in place. They are sized GS_VEC_NC times the halo, quadrupling what the backend holds, and only gs_op_r3 ever touches them, so a backend that can allocate them on its own defers that to the first fused exchange (see init_vec) rather than paying for it in every run. A backend whose vector buffers are part of an allocation the whole run has to agree on – symmetric memory, coarrays, registered memory, an RMA window – cannot defer, since a rank with no shared dofs never reaches the first fused exchange; those allocate in init and set this there. | |
Detailed Description
Definition at line 65 of file gs_crystal.f90.
Member Function/Subroutine Documentation
◆ free() [1/2]
Definition at line 86 of file gs_crystal.f90.
◆ free() [2/2]
Definition at line 82 of file gs_comm.f90.
◆ free_dofs()
|
inherited |
Definition at line 87 of file gs_comm.f90.
◆ free_order()
|
inherited |
Definition at line 89 of file gs_comm.f90.
◆ init() [1/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::init | ( | class(gs_crystal_t), intent(inout) | this, |
| type(stack_i4_t), intent(inout) | send_pe, | ||
| type(stack_i4_t), intent(inout) | recv_pe | ||
| ) |
Definition at line 85 of file gs_crystal.f90.
◆ init() [2/2]
Definition at line 81 of file gs_comm.f90.
◆ init_dofs()
|
inherited |
Definition at line 86 of file gs_comm.f90.
◆ init_order()
|
inherited |
- Parameters
-
send_pe,only contains rank ids this porcesss should send to recv_pe,only the ranks this process should receive from
Definition at line 88 of file gs_comm.f90.
◆ init_schedule()
|
inherited |
Definition at line 91 of file gs_comm.f90.
◆ init_vec() [1/2]
|
inherited |
- Note
- Rank local by contract: a rank with no shared dofs skips the fused exchange entirely, so an override must not communicate.
Definition at line 94 of file gs_comm.f90.
◆ init_vec() [2/2]
Definition at line 91 of file gs_crystal.f90.
◆ nbrecv() [1/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbrecv | ( | class(gs_crystal_t), intent(inout) | this, |
| integer, intent(in) | tag | ||
| ) |
Definition at line 89 of file gs_crystal.f90.
◆ nbrecv() [2/2]
Definition at line 84 of file gs_comm.f90.
◆ nbrecv_vec() [1/2]
|
inherited |
Definition at line 96 of file gs_comm.f90.
◆ nbrecv_vec() [2/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbrecv_vec | ( | class(gs_crystal_t), intent(inout) | this, |
| integer, intent(in) | tag, | ||
| integer, intent(in) | nc | ||
| ) |
Definition at line 93 of file gs_crystal.f90.
◆ nbsend() [1/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbsend | ( | class(gs_crystal_t), intent(inout) | this, |
| real(kind=rp), dimension(n), intent(inout) | u, | ||
| integer, intent(in) | n, | ||
| integer, intent(in) | tag, | ||
| type(c_ptr), intent(inout) | deps, | ||
| type(c_ptr), intent(inout) | strm | ||
| ) |
Definition at line 88 of file gs_crystal.f90.
◆ nbsend() [2/2]
Definition at line 83 of file gs_comm.f90.
◆ nbsend_vec() [1/2]
|
inherited |
- Parameters
-
u compact shared buffer, component-outer: u((c-1)*n + idx) n number of shared dofs (per component) nc number of components
Definition at line 95 of file gs_comm.f90.
◆ nbsend_vec() [2/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbsend_vec | ( | class(gs_crystal_t), intent(inout) | this, |
| real(kind=rp), dimension(nc*n), intent(inout) | u, | ||
| integer, intent(in) | n, | ||
| integer, intent(in) | nc, | ||
| integer, intent(in) | tag, | ||
| type(c_ptr), intent(inout) | deps, | ||
| type(c_ptr), intent(inout) | strm | ||
| ) |
- Parameters
-
u compact shared buffer, component-outer: u((c-1)*n + idx)
Definition at line 92 of file gs_crystal.f90.
◆ nbwait() [1/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbwait | ( | class(gs_crystal_t), intent(inout) | this, |
| real(kind=rp), dimension(n), intent(inout) | u, | ||
| integer, intent(in) | n, | ||
| integer | op, | ||
| type(c_ptr), intent(inout) | strm | ||
| ) |
Definition at line 90 of file gs_crystal.f90.
◆ nbwait() [2/2]
Definition at line 85 of file gs_comm.f90.
◆ nbwait_vec() [1/2]
|
inherited |
Definition at line 97 of file gs_comm.f90.
◆ nbwait_vec() [2/2]
| procedure, pass(this) gs_crystal::gs_crystal_t::nbwait_vec | ( | class(gs_crystal_t), intent(inout) | this, |
| real(kind=rp), dimension(nc*n), intent(inout) | u, | ||
| integer, intent(in) | n, | ||
| integer, intent(in) | nc, | ||
| integer | op, | ||
| type(c_ptr), intent(inout) | strm | ||
| ) |
Definition at line 94 of file gs_crystal.f90.
◆ take_schedule()
|
inherited |
- Parameters
-
src the backend to take the schedule from, left without one
Definition at line 90 of file gs_comm.f90.
Member Data Documentation
◆ buf
| real(kind=rp), dimension(:), allocatable gs_crystal::gs_crystal_t::buf |
Definition at line 70 of file gs_crystal.f90.
◆ buf_v
| real(kind=rp), dimension(:), allocatable gs_crystal::gs_crystal_t::buf_v |
Definition at line 76 of file gs_crystal.f90.
◆ nrreq
| integer gs_crystal::gs_crystal_t::nrreq = 0 |
Definition at line 80 of file gs_crystal.f90.
◆ nsreq
| integer gs_crystal::gs_crystal_t::nsreq = 0 |
Definition at line 80 of file gs_crystal.f90.
◆ plan
| type(gs_crystal_plan_t) gs_crystal::gs_crystal_t::plan |
Definition at line 67 of file gs_crystal.f90.
◆ recv_dof
|
inherited |
Definition at line 58 of file gs_comm.f90.
◆ recv_pe
|
inherited |
Definition at line 64 of file gs_comm.f90.
◆ rreq
| type(mpi_request), dimension(2) gs_crystal::gs_crystal_t::rreq |
Definition at line 79 of file gs_crystal.f90.
◆ sbuf
| real(kind=rp), dimension(:), allocatable gs_crystal::gs_crystal_t::sbuf |
Definition at line 72 of file gs_crystal.f90.
◆ sbuf_v
| real(kind=rp), dimension(:), allocatable gs_crystal::gs_crystal_t::sbuf_v |
Definition at line 77 of file gs_crystal.f90.
◆ send_dof
|
inherited |
Definition at line 55 of file gs_comm.f90.
◆ send_pe
|
inherited |
- Note
- : this will usually be fewer than the total number of ranks size(send_pe) <= pe_size
Definition at line 62 of file gs_comm.f90.
◆ sreq
| type(mpi_request), dimension(1) gs_crystal::gs_crystal_t::sreq |
Definition at line 79 of file gs_crystal.f90.
◆ tag
| integer gs_crystal::gs_crystal_t::tag = 0 |
Definition at line 83 of file gs_crystal.f90.
◆ vec_ready
|
inherited |
Definition at line 79 of file gs_comm.f90.
◆ vec_supported
|
inherited |
Definition at line 68 of file gs_comm.f90.
The documentation for this type was generated from the following file:
- /home/runner/work/neko/neko/src/gs/gs_crystal.f90
