|
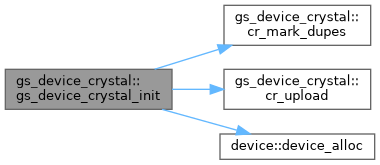
| subroutine | gs_device_crystal_init (this, send_pe, recv_pe) |
| | Initialise crystal router based device communication See gs_comm.f90 for details.
|
| |
| subroutine | gs_device_crystal_init_vec (this) |
| | Allocate the fused vector working and send buffers in device memory, sized for GS_VEC_NC components. Deferred to the first fused exchange, see gs_comm_t. The nc-scaled stage index lists are uploaded separately, on the first exchange of a given nc (see vec_nc), and the routing plan is shared with the scalar exchange, so this stays rank local.
|
| |
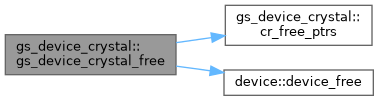
| subroutine | gs_device_crystal_free (this) |
| | Deallocate crystal router based device communication.
|
| |
| subroutine | gs_device_crystal_nbrecv (this, tag) |
| | Post the receives of the first routing stage.
|
| |
| subroutine | gs_device_crystal_nbsend (this, u, n, tag, deps, strm) |
| | Pack the shared vector and post the send of the first routing stage.
|
| |
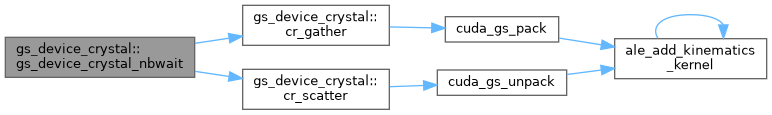
| subroutine | gs_device_crystal_nbwait (this, u, n, op, strm) |
| | Drive the remaining routing stages and reduce what is delivered into the shared vector.
|
| |
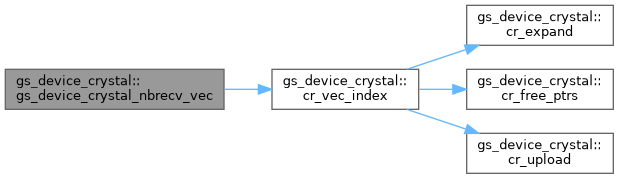
| subroutine | gs_device_crystal_nbrecv_vec (this, tag, nc) |
| | Post the receives of the first routing stage, fused nc-component.
|
| |
| subroutine | gs_device_crystal_nbsend_vec (this, u, n, nc, tag, deps, strm) |
| | Pack the shared vector and post the send of the first routing stage, fused nc-component.
|
| |
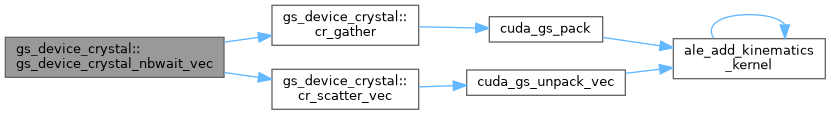
| subroutine | gs_device_crystal_nbwait_vec (this, u, n, nc, op, strm) |
| | Drive the remaining routing stages and reduce what is delivered into the shared vector, fused nc-component.
|
| |
| subroutine | cr_gather (src_d, dst_d, idx_d, n, strm) |
| | Gather n words of src into dst through the 1-based index list idx_d, i.e. dst(j) = src(idx(j))
|
| |
| subroutine | cr_gather_vec (src_d, dst_d, idx_d, n, nc, ns, strm) |
| | Gather n positions of the component-outer src (stride ns) into the interleaved dst.
|
| |
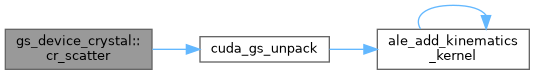
| subroutine | cr_scatter (u_d, op, buf_d, idx_d, n, strm) |
| | Reduce n delivered words into the shared vector under op.
|
| |
| subroutine | cr_scatter_vec (u_d, op, buf_d, idx_d, n, nc, ns, strm) |
| | Reduce n delivered positions into the component-outer shared vector.
|
| |
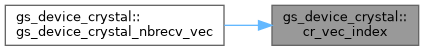
| subroutine | cr_vec_index (this, nc) |
| | Build the per-stage index lists of the fused vector exchange, which address the same words as the scalar ones with the components spelled out: position p of a stage becomes nc*(p-1) + 1 .. nc*p.
|
| |
| subroutine | cr_expand (idx, n, nc, out) |
| | Spell out the components of the 1-based index list idx over nc.
|
| |
| subroutine | cr_upload (ptr, idx, n) |
| | Copy the first n entries of an index list to the device, leaving ptr null when there are none.
|
| |
| subroutine | cr_free_ptrs (ptrs) |
| | Release a list of device pointers, leaving them null.
|
| |
| subroutine | cr_mark_dupes (dof, out, n) |
| | Copy dof into out, negating every index that appears more than once so that the unpack kernel reduces those atomically.
|
| |
The device counterpart of gs_crystal: the same routing plan, with the halo never leaving the device. Every word movement the routing asks for is an indexed gather, which is what the existing gs pack kernel already does (buf[j] = u[dof[j]-1]), so forwarding a stage costs one kernel launch and no new device code – the working buffer simply takes the place of the shared vector as the kernel's source.
The two working buffer columns are separate allocations, so each stage addresses its source and destination from offset zero and the received words land straight behind the ones that stay. As on the host, only the first stage overlaps the local gather-scatter.