Functions/Subroutines | |
| subroutine, public | tnsr2d_el_cpu (v, nv, u, nu, a, bt) |
| Two-dimensional tensor product on a single element. | |
| subroutine, public | tnsr3d_el_cpu (v, nv, u, nu, a, bt, ct) |
| Three-dimensional tensor product on a single element. | |
| subroutine | tnsr3d_el_nvnu_cpu (v, nv, u, nu, a, bt, ct) |
| Single-element tensor product for arbitrary nu and nv. | |
| subroutine | tnsr3d_el_1_nu_cpu (v, u, nu, a, bt, ct) |
| Single-element evaluation at one point, for arbitrary nu. | |
| subroutine | tnsr3d_el_1_4_cpu (v, u, a, bt, ct) |
| Single-element evaluation at one point, specialised for nu = 4. | |
| subroutine | tnsr3d_el_1_6_cpu (v, u, a, bt, ct) |
| Single-element evaluation at one point, specialised for nu = 6. | |
| subroutine | tnsr3d_el_1_8_cpu (v, u, a, bt, ct) |
| Single-element evaluation at one point, specialised for nu = 8. | |
| subroutine | tnsr3d_el_1_10_cpu (v, u, a, bt, ct) |
| Single-element evaluation at one point, specialised for nu = 10. | |
| subroutine | tnsr3d_el_1_12_cpu (v, u, a, bt, ct) |
| Single-element evaluation at one point, specialised for nu = 12. | |
| subroutine | tnsr3d_el_n_cpu (v, u, a, bt, ct, n) |
| Single-element tensor product with nv = nu, for arbitrary order. | |
| subroutine | tnsr3d_el_n14_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 14. | |
| subroutine | tnsr3d_el_n13_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 13. | |
| subroutine | tnsr3d_el_n12_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 12. | |
| subroutine | tnsr3d_el_n11_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 11. | |
| subroutine | tnsr3d_el_n10_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 10. | |
| subroutine | tnsr3d_el_n9_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 9. | |
| subroutine | tnsr3d_el_n8_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 8. | |
| subroutine | tnsr3d_el_n7_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 7. | |
| subroutine | tnsr3d_el_n6_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 6. | |
| subroutine | tnsr3d_el_n5_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 5. | |
| subroutine | tnsr3d_el_n4_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 4. | |
| subroutine | tnsr3d_el_n3_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 3. | |
| subroutine | tnsr3d_el_n2_cpu (v, u, a, bt, ct) |
| Single-element tensor product specialised for nv = nu = 2. | |
| subroutine, public | tnsr3d_cpu (v, nv, u, nu, a, bt, ct, nelv) |
| Three-dimensional tensor product over a list of elements. | |
| subroutine | tnsr3d_nvnu_cpu (v, nv, u, nu, a, bt, ct, nelv) |
| Generic tensor-product evaluation for arbitrary nu, nv. | |
| subroutine | tnsr3d_nu2nv4_cpu (v, u, a, bt, ct, nelv) |
| Batched tensor product specialised for nu = 2, nv = 4. | |
| subroutine | tnsr3d_nu4_cpu (v, nv, u, a, bt, ct, nelv) |
| Batched tensor product specialised for nu = 4, generic in nv. | |
| subroutine | tnsr3d_nu8_cpu (v, nv, u, a, bt, ct, nelv) |
| Tensor-product evaluation specialised for nu = 8, generic in nv. | |
| subroutine | tnsr3d_nu12_cpu (v, nv, u, a, bt, ct, nelv) |
| Tensor-product evaluation specialised for nu = 12, generic in nv. | |
| subroutine, public | tnsr1_3d_cpu (v, nv, nu, a, bt, ct, nelv) |
| Three-dimensional tensor product applied in place. | |
| subroutine | tnsr1_3d_nvnu_cpu (v, nv, nu, a, bt, ct, nelv) |
| In-place tensor product for arbitrary nu and nv. | |
| subroutine | tnsr1_3d_nu4nv2_cpu (v, a, bt, ct, nelv) |
| In-place tensor product specialised for nu = 4, nv = 2. | |
Function/Subroutine Documentation
◆ tnsr1_3d_cpu()
| subroutine, public tensor_cpu::tnsr1_3d_cpu | ( | real(kind=rp), dimension(nv*nv*nv*nelv), intent(inout) | v, |
| integer, intent(in) | nv, | ||
| integer, intent(in) | nu, | ||
| real(kind=rp), dimension(nv, nu), intent(inout) | a, | ||
| real(kind=rp), dimension(nu, nv), intent(inout) | bt, | ||
| real(kind=rp), dimension(nu, nv), intent(inout) | ct, | ||
| integer, intent(in) | nelv | ||
| ) |
As tnsr3d_cpu, but v is both input and output: each element is read at order nu and written back at order nv. Elements are walked backwards when nv > nu, so that a growing element never overwrites input it has not read yet.
- Parameters
-
v Input and result, nu*nu*nu per element on entry, nv*nv*nv on exit. nv Output polynomial order. nu Input polynomial order. A Operator along the first reference direction, (nv, nu). Bt Transposed operator along the second direction, (nu, nv). Ct Transposed operator along the third direction, (nu, nv). nelv Number of elements.
Definition at line 1675 of file tensor_cpu.f90.


◆ tnsr1_3d_nu4nv2_cpu()
|
private |
See tnsr1_3d_cpu for the operation and the argument meanings.
Definition at line 1767 of file tensor_cpu.f90.

◆ tnsr1_3d_nvnu_cpu()
|
private |
The fallback of tnsr1_3d_cpu, including the reversed element traversal when the order grows. See tnsr1_3d_cpu for the argument meanings.
Definition at line 1692 of file tensor_cpu.f90.

◆ tnsr2d_el_cpu()
| subroutine, public tensor_cpu::tnsr2d_el_cpu | ( | real(kind=rp), dimension(nv*nv), intent(inout) | v, |
| integer, intent(in) | nv, | ||
| real(kind=rp), dimension(nu*nu), intent(inout) | u, | ||
| integer, intent(in) | nu, | ||
| real(kind=rp), dimension(nv, nu), intent(inout) | a, | ||
| real(kind=rp), dimension(nu, nv), intent(inout) | bt | ||
| ) |
Applies \( v = (A \otimes B^T) u \): the one-dimensional operator A along the first reference direction and B along the second, taking the element from order nu to order nv. Routed through mxm, so it uses whichever matrix-matrix backend the build selected.
- Parameters
-
v Result, nv*nv values. nv Output polynomial order. u Input, nu*nu values. nu Input polynomial order. A Operator along the first reference direction, (nv, nu). Bt Transposed operator along the second direction, (nu, nv).
Definition at line 22 of file tensor_cpu.f90.


◆ tnsr3d_cpu()
| subroutine, public tensor_cpu::tnsr3d_cpu | ( | real(kind=rp), dimension(nv*nv*nv, nelv), intent(inout) | v, |
| integer, intent(in) | nv, | ||
| real(kind=rp), dimension(nu*nu*nu, nelv), intent(in) | u, | ||
| integer, intent(in) | nu, | ||
| real(kind=rp), dimension(nv, nu), intent(in) | a, | ||
| real(kind=rp), dimension(nu, nv), intent(in) | bt, | ||
| real(kind=rp), dimension(nu, nv), intent(in) | ct, | ||
| integer, intent(in) | nelv | ||
| ) |
The batched counterpart of tnsr3d_el_cpu: applies \( v = (A \otimes B^T \otimes C^T) u \) to every element of u, taking each from order nu to order nv. This is the entry point used for dealiasing (nu and nv related by the 3/2 rule) and for the phmg and hsmg grid transfers. Dispatches on nu to an unrolled kernel where one exists, otherwise to the generic tnsr3d_nvnu_cpu.
- Note
- Unlike the
_el_routines this opens its own parallel region, over the element loop.
- Parameters
-
v Result, nv*nv*nv per element. nv Output polynomial order. u Input, nu*nu*nu per element. nu Input polynomial order. A Operator along the first reference direction, (nv, nu). Bt Transposed operator along the second direction, (nu, nv). Ct Transposed operator along the third direction, (nu, nv). nelv Number of elements.
Definition at line 1291 of file tensor_cpu.f90.


◆ tnsr3d_el_1_10_cpu()
|
private |
Unrolled form of tnsr3d_el_1_nu_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 343 of file tensor_cpu.f90.

◆ tnsr3d_el_1_12_cpu()
|
private |
Unrolled form of tnsr3d_el_1_nu_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 395 of file tensor_cpu.f90.

◆ tnsr3d_el_1_4_cpu()
|
private |
Unrolled form of tnsr3d_el_1_nu_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 222 of file tensor_cpu.f90.

◆ tnsr3d_el_1_6_cpu()
|
private |
Unrolled form of tnsr3d_el_1_nu_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 256 of file tensor_cpu.f90.

◆ tnsr3d_el_1_8_cpu()
|
private |
Unrolled form of tnsr3d_el_1_nu_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 296 of file tensor_cpu.f90.

◆ tnsr3d_el_1_nu_cpu()
|
private |
The nv = 1 case of tnsr3d_el_cpu: each operator is a single row, so the three contractions collapse the element to one value. Used to interpolate a field to a scattered point inside an element.
- Parameters
-
v Result, a single value. u Input, nu*nu*nu values. nu Input polynomial order. A Operator along the first reference direction, (1, nu). Bt Transposed operator along the second direction, (nu, 1). Ct Transposed operator along the third direction, (nu, 1).
Definition at line 182 of file tensor_cpu.f90.

◆ tnsr3d_el_cpu()
| subroutine, public tensor_cpu::tnsr3d_el_cpu | ( | real(kind=rp), dimension(nv*nv*nv), intent(inout) | v, |
| integer, intent(in) | nv, | ||
| real(kind=rp), dimension(nu*nu*nu), intent(inout) | u, | ||
| integer, intent(in) | nu, | ||
| real(kind=rp), dimension(nv, nu), intent(inout) | a, | ||
| real(kind=rp), dimension(nu, nv), intent(inout) | bt, | ||
| real(kind=rp), dimension(nu, nv), intent(inout) | ct | ||
| ) |
Applies \( v = (A \otimes B^T \otimes C^T) u \), one one-dimensional operator per reference direction, taking the element from order nu to order nv. Dispatches on the shape: nv = nu selects the square kernels (filtering and SVV, where the order is unchanged), nv = 1 the single-point kernels (evaluating an element at one location, as local_interpolation does), and anything else the generic kernel.
- Note
- Contains no OpenMP and is marked
!OCL SERIAL, because callers invoke it per element from inside their own parallel region.
- Parameters
-
v Result, nv*nv*nv values. nv Output polynomial order. u Input, nu*nu*nu values. nu Input polynomial order. A Operator along the first reference direction, (nv, nu). Bt Transposed operator along the second direction, (nu, nv). Ct Transposed operator along the third direction, (nu, nv).
Definition at line 49 of file tensor_cpu.f90.


◆ tnsr3d_el_n10_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 801 of file tensor_cpu.f90.

◆ tnsr3d_el_n11_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 733 of file tensor_cpu.f90.

◆ tnsr3d_el_n12_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 662 of file tensor_cpu.f90.

◆ tnsr3d_el_n13_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 588 of file tensor_cpu.f90.

◆ tnsr3d_el_n14_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 511 of file tensor_cpu.f90.

◆ tnsr3d_el_n2_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 1237 of file tensor_cpu.f90.

◆ tnsr3d_el_n3_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 1193 of file tensor_cpu.f90.

◆ tnsr3d_el_n4_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 1146 of file tensor_cpu.f90.

◆ tnsr3d_el_n5_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 1096 of file tensor_cpu.f90.

◆ tnsr3d_el_n6_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 1043 of file tensor_cpu.f90.

◆ tnsr3d_el_n7_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 987 of file tensor_cpu.f90.

◆ tnsr3d_el_n8_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 928 of file tensor_cpu.f90.

◆ tnsr3d_el_n9_cpu()
|
private |
Unrolled form of tnsr3d_el_n_cpu; see tnsr3d_el_cpu for the operation and the argument meanings.
Definition at line 866 of file tensor_cpu.f90.

◆ tnsr3d_el_n_cpu()
|
private |
The order-preserving case of tnsr3d_el_cpu, which is what filtering and the one-sided SVV operators need. The fallback for orders without an unrolled kernel below.
- Parameters
-
v Result, n*n*n values. u Input, n*n*n values. A Operator along the first reference direction, (n, n). Bt Transposed operator along the second direction, (n, n). Ct Transposed operator along the third direction, (n, n). n Polynomial order, the same on input and output.
Definition at line 460 of file tensor_cpu.f90.

◆ tnsr3d_el_nvnu_cpu()
|
private |
The fallback of tnsr3d_el_cpu, used when neither the square nor the single-point shape applies. Contracts one direction at a time through two work buffers.
- Parameters
-
v Result, nv*nv*nv values. nv Output polynomial order. u Input, nu*nu*nu values. nu Input polynomial order. v Result, nv*nv*nv values. u Input, nu*nu*nu values. A Operator along the first reference direction, (nv, nu). Bt Transposed operator along the second direction, (nu, nv). Ct Transposed operator along the third direction, (nu, nv).
Definition at line 120 of file tensor_cpu.f90.

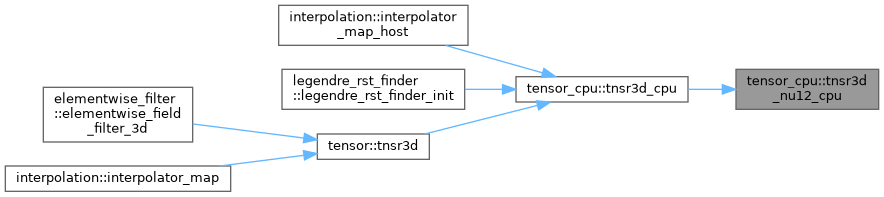
◆ tnsr3d_nu12_cpu()
|
private |
Covers the 3/2-rule dealiasing pair for lx = 12 (nu = 12 to nv = 18) and the reverse direction of the lx = 8 pair (nu = 12 to nv = 8). Unrolled over nu on the same grounds as tnsr3d_nu8_cpu. See tnsr3d_cpu for the operation and the argument meanings.
Definition at line 1586 of file tensor_cpu.f90.
◆ tnsr3d_nu2nv4_cpu()
|
private |
Prolongation from the coarsest multigrid level. See tnsr3d_cpu for the operation and the argument meanings.
Definition at line 1402 of file tensor_cpu.f90.

◆ tnsr3d_nu4_cpu()
|
private |
Covers the phmg transfers to and from an lx = 4 level. See tnsr3d_cpu for the operation and the argument meanings.
Definition at line 1454 of file tensor_cpu.f90.

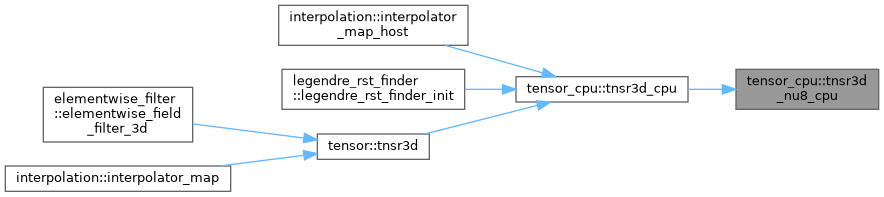
◆ tnsr3d_nu8_cpu()
|
private |
Covers the 3/2-rule dealiasing pair for lx = 8 (nu = 8 to nv = 12) and the phmg transfers that start from an lx = 8 level. All three contractions are unrolled over nu, so the innermost loop runs over the unit-stride index with no reduction chain and the result is written once rather than accumulated over nu passes. See tnsr3d_cpu for the operation and the argument meanings.
Definition at line 1515 of file tensor_cpu.f90.
◆ tnsr3d_nvnu_cpu()
|
private |
Each of the three contractions sums over k, the index that strides through memory. Written with k innermost the reduction is a dependent scalar chain over strided loads, which neither SVE nor any other unit-stride SIMD unit can do anything with. The k loop is therefore hoisted out and peeled at k = 1, leaving an innermost loop that runs over the unit-stride index of both operand and result with a loop-invariant scalar multiplier, i.e. a plain axpy. The summation order over k is unchanged, so results match the reduction form. This is the same shape the unrolled tnsr3d_nu4_cpu already has, expressed without knowing nu at compile time. See tnsr3d_cpu for the argument meanings.
Definition at line 1323 of file tensor_cpu.f90.

