Loading...
Searching...
No Matches
#include <string.h>#include <stdlib.h>#include <stdio.h>#include "ax_helm_compr_kernel.h"#include "elem_block_tune.h"#include <device/device_config.h>#include <device/cuda/check.h>#include <common/neko_log.h>Go to the source code of this file.
Macros | |
| #define | CASE_1D(LX, C) |
| #define | CASE_1D_SEL(LX, SEL) |
| #define | CASE_KSTEP(LX, C) |
| #define | CASE_KSTEP_PADDED(LX, C) |
| #define | CASE_KSTEP_SEL(LX, SEL) |
| #define | CASE_KSTEP_PADDED_SEL(LX, SEL) |
| #define | CASE_DMMA(LX, C) |
| #define | CASE_DMMA_SEL(LX, SEL) |
| #define | CASE_DMMA_TMA(LX, C) |
| #define | CASE_DMMA_TMA_SEL(LX, SEL) |
| #define | CASE(LX) |
| #define | CASE_PADDED(LX) |
| #define | CASE_LARGE(LX) |
| #define | CASE_LARGE_PADDED(LX) |
| #define | CASE_VECTOR_KSTEP(LX, C) |
| #define | CASE_VECTOR_KSTEP_PADDED(LX, C) |
| #define | CASE_VECTOR_KSTEP_SEL(LX, SEL) |
| #define | CASE_VECTOR_KSTEP_PADDED_SEL(LX, SEL) |
| #define | CASE_VECTOR_DMMA(LX, C) |
| #define | CASE_VECTOR_DMMA_SEL(LX, SEL) |
| #define | CASE_VECTOR_DMMA_TMA(LX, C) |
| #define | CASE_VECTOR_DMMA_TMA_SEL(LX, SEL) |
| #define | CASE_VECTOR_DMMA_TMA_BATCH(LX, C) |
| #define | CASE_VECTOR_DMMA_TMA_BATCH_SEL(LX, SEL) |
| #define | CASE_VECTOR(LX) |
| #define | CASE_VECTOR_PADDED(LX) |
Macro Definition Documentation
◆ CASE
Value:
} \
break
__global__ void ale_add_kinematics_kernel(const int n, T *__restrict__ wx, T *__restrict__ wy, T *__restrict__ wz, const T *__restrict__ x_ref, const T *__restrict__ y_ref, const T *__restrict__ z_ref, const T *__restrict__ phi, const T *__restrict__ x, const T *__restrict__ y, const T *__restrict__ z, const kinematics_params_t kin_params)
Definition ale_kinematics_kernel.h:52
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g23
Definition ax_helm_compr_kernel.h:209
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g22
Definition ax_helm_compr_kernel.h:205
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const int *__restrict__ ind
Definition ax_helm_compr_kernel.h:210
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g13
Definition ax_helm_compr_kernel.h:208
__global__ void T *__restrict__ T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ w
Definition ax_helm_compr_kernel.h:978
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const int *__restrict__ const int nelv
Definition ax_helm_compr_kernel.h:211
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g12
Definition ax_helm_compr_kernel.h:207
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ dz
Definition ax_helm_compr_kernel.h:202
__global__ void const T *__restrict__ const T *__restrict__ dx
Definition ax_helm_compr_kernel.h:200
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ dy
Definition ax_helm_compr_kernel.h:201
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g33
Definition ax_helm_compr_kernel.h:206
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ g11
Definition ax_helm_compr_kernel.h:204
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ h1
Definition ax_helm_compr_kernel.h:203
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ dyt
Definition cdtp_kernel.h:115
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ dzt
Definition cdtp_kernel.h:116
__global__ void const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ const T *__restrict__ dxt
Definition cdtp_kernel.h:114
◆ CASE_1D
Value:
__global__ void ax_helm_compr_kernel_1d(T *__restrict__ w, const T *__restrict__ u, const T *__restrict__ dx, const T *__restrict__ dy, const T *__restrict__ dz, const T *__restrict__ dxt, const T *__restrict__ dyt, const T *__restrict__ dzt, const T *__restrict__ h1, const T *__restrict__ g11, const T *__restrict__ g22, const T *__restrict__ g33, const T *__restrict__ g12, const T *__restrict__ g13, const T *__restrict__ g23, const int *__restrict__ ind)
Definition ax_helm_compr_kernel.h:88
◆ CASE_1D_SEL
◆ CASE_DMMA
Value:
◆ CASE_DMMA_SEL
◆ CASE_DMMA_TMA
Value:
◆ CASE_DMMA_TMA_SEL
Value:
switch (SEL) { \
}
#define CASE_DMMA_TMA(LX, C)
◆ CASE_KSTEP
Value:
◆ CASE_KSTEP_PADDED
Value:
◆ CASE_KSTEP_PADDED_SEL
Value:
switch (SEL) { \
}
#define CASE_KSTEP_PADDED(LX, C)
◆ CASE_KSTEP_SEL
Value:
switch (SEL) { \
}
#define CASE_KSTEP(LX, C)
◆ CASE_LARGE
◆ CASE_LARGE_PADDED
◆ CASE_PADDED
Value:
} \
break
◆ CASE_VECTOR
Value:
&autotune_vec_eb[LX], \
&autotune_vec_nw[LX], \
&autotune_vec_tw[LX], \
&autotune_vec_bw[LX]); \
} \
break
__global__ void T *__restrict__ T *__restrict__ const T *__restrict__ const T *__restrict__ v
Definition ax_helm_compr_kernel.h:977
◆ CASE_VECTOR_DMMA
Value:
◆ CASE_VECTOR_DMMA_SEL
Value:
switch (SEL) { \
}
#define CASE_VECTOR_DMMA(LX, C)
◆ CASE_VECTOR_DMMA_TMA
Value:
◆ CASE_VECTOR_DMMA_TMA_BATCH
Value:
NEKO_DMMA_TMA_BATCH_SMEM, stream>>> \
static bool ax_helm_compr_dmma_tma_batch_optin()
Definition ax_helm_compr_kernel.h:2289
◆ CASE_VECTOR_DMMA_TMA_BATCH_SEL
Value:
switch (SEL) { \
}
#define CASE_VECTOR_DMMA_TMA_BATCH(LX, C)
◆ CASE_VECTOR_DMMA_TMA_SEL
Value:
switch (SEL) { \
}
#define CASE_VECTOR_DMMA_TMA(LX, C)
◆ CASE_VECTOR_KSTEP
Value:
◆ CASE_VECTOR_KSTEP_PADDED
Value:
◆ CASE_VECTOR_KSTEP_PADDED_SEL
Value:
switch (SEL) { \
}
#define CASE_VECTOR_KSTEP_PADDED(LX, C)
◆ CASE_VECTOR_KSTEP_SEL
Value:
switch (SEL) { \
}
#define CASE_VECTOR_KSTEP(LX, C)
◆ CASE_VECTOR_PADDED
Value:
nelv, lx, \
&autotune_vec_eb[LX], \
&autotune_vec_nw[LX], \
&autotune_vec_tw[LX], \
&autotune_vec_bw[LX]); \
} \
break
Function Documentation
◆ cuda_ax_helm_compr()
| void cuda_ax_helm_compr | ( | void * | w, |
| void * | u, | ||
| void * | dx, | ||
| void * | dy, | ||
| void * | dz, | ||
| void * | dxt, | ||
| void * | dyt, | ||
| void * | dzt, | ||
| void * | h1, | ||
| void * | g11, | ||
| void * | g22, | ||
| void * | g33, | ||
| void * | g12, | ||
| void * | g13, | ||
| void * | g23, | ||
| void * | ind, | ||
| int * | nelv, | ||
| int * | lx | ||
| ) |
Fortran wrapper for device CUDA Ax, compressed geometric factors
Definition at line 97 of file ax_helm_compr.cu.
Here is the call graph for this function:
Here is the caller graph for this function:
◆ cuda_ax_helm_compr_vector()
| void cuda_ax_helm_compr_vector | ( | void * | au, |
| void * | av, | ||
| void * | aw, | ||
| void * | u, | ||
| void * | v, | ||
| void * | w, | ||
| void * | dx, | ||
| void * | dy, | ||
| void * | dz, | ||
| void * | dxt, | ||
| void * | dyt, | ||
| void * | dzt, | ||
| void * | h1, | ||
| void * | g11, | ||
| void * | g22, | ||
| void * | g33, | ||
| void * | g12, | ||
| void * | g13, | ||
| void * | g23, | ||
| void * | ind, | ||
| int * | nelv, | ||
| int * | lx | ||
| ) |
Fortran wrapper for device CUDA Ax vector version, compressed geometric factors
Definition at line 309 of file ax_helm_compr.cu.
Here is the call graph for this function:
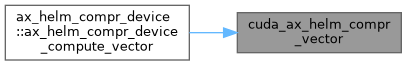
Here is the caller graph for this function:
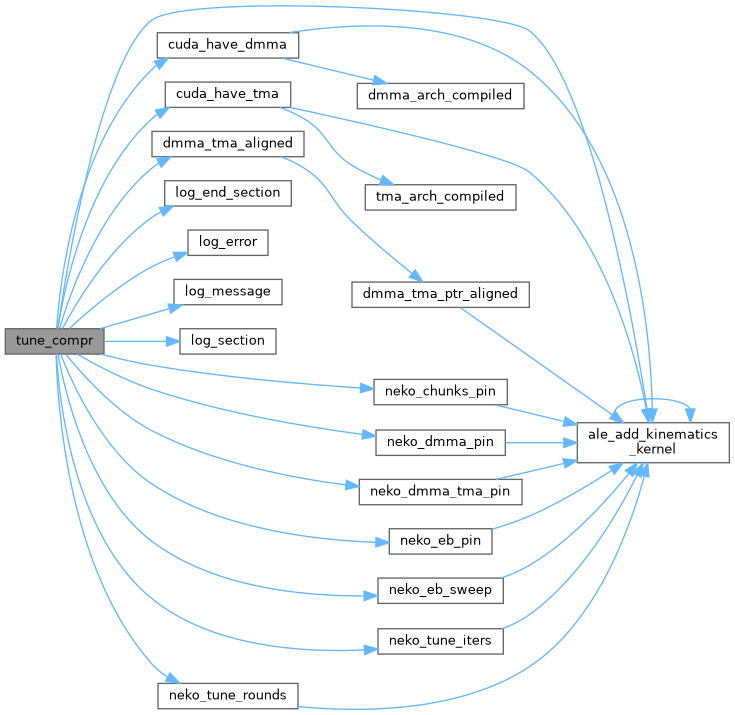
◆ tune_compr()
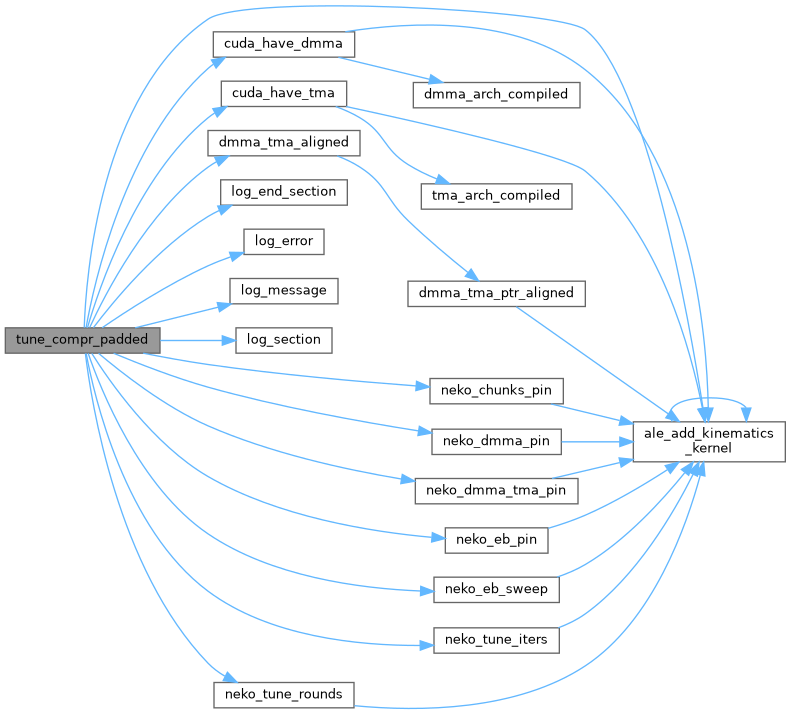
◆ tune_compr_padded()
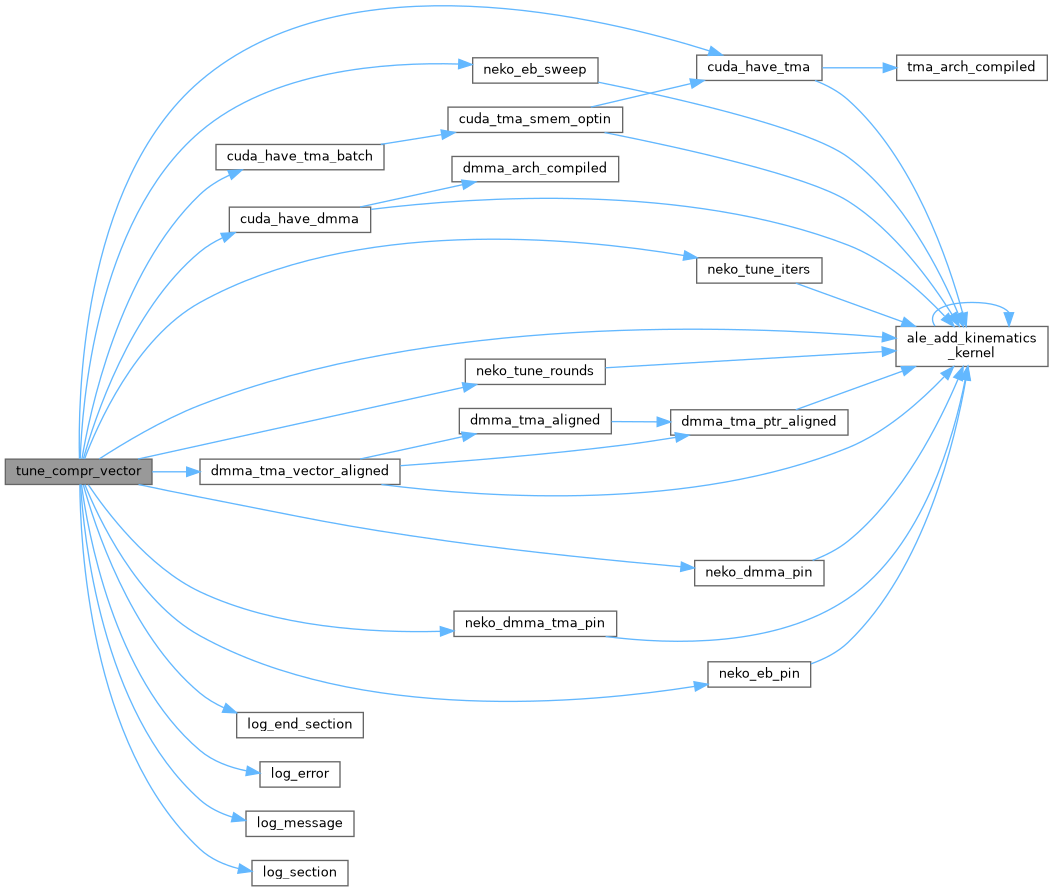
◆ tune_compr_vector()
◆ tune_compr_vector_padded()
| int tune_compr_vector_padded | ( | void * | au, |
| void * | av, | ||
| void * | aw, | ||
| void * | u, | ||
| void * | v, | ||
| void * | w, | ||
| void * | dx, | ||
| void * | dy, | ||
| void * | dz, | ||
| void * | h1, | ||
| void * | g11, | ||
| void * | g22, | ||
| void * | g33, | ||
| void * | g12, | ||
| void * | g13, | ||
| void * | g23, | ||
| void * | ind, | ||
| int * | nelv, | ||
| int * | lx, | ||
| int * | eb_sel, | ||
| int * | nw_sel, | ||
| int * | tw_sel, | ||
| int * | bw_sel | ||
| ) |